

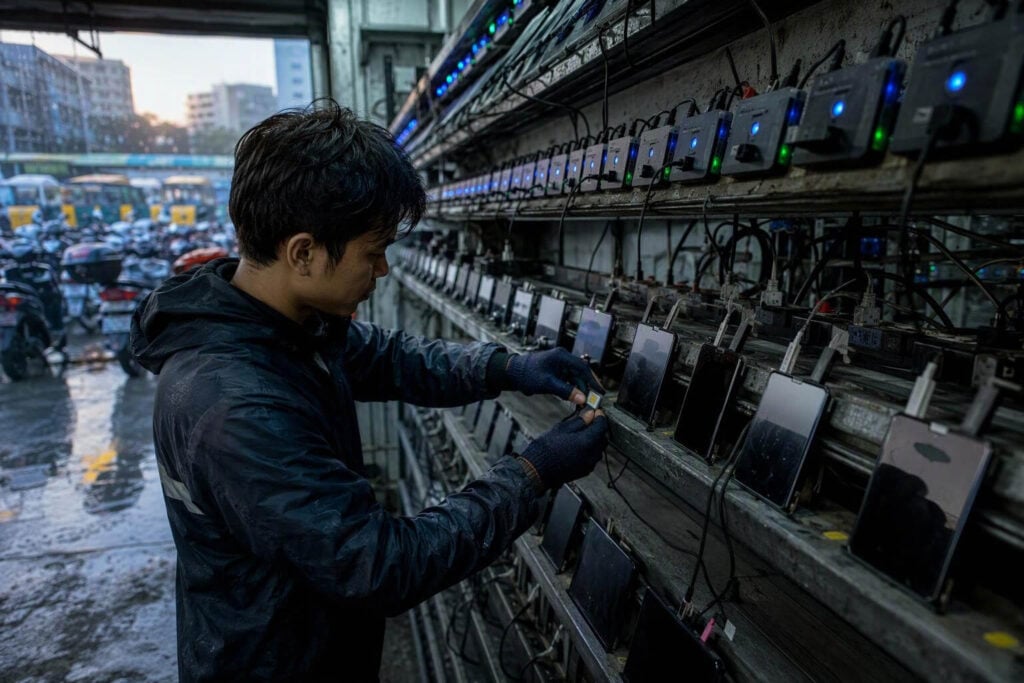


The PaperPhone network is a large headless-browser operation designed to make automated web requests resemble ordinary mobile traffic. CrowdSec linked the activity to 75,000 IP addresses across 43 countries, demonstrating how distributed automation can bypass basic IP and location-based controls.
How the PaperPhone network was discovered
CrowdSec analysts identified the activity after collecting bot signals following a detection update on 31 August 2026. The resulting investigation examined traffic observed over a two-week period and connected requests that initially appeared to come from many unrelated sources.
On 29 September 2026, CrowdSec published its findings about the cluster. The report linked the operation to approximately 75,000 IP addresses, 230 IP blocks and 43 countries. The PaperPhone name reflects the network’s use of fabricated phone and browser identities to disguise automated activity as mobile browsing.
The infrastructure may have been operating before the two-week observation period. However, the available reporting does not establish when the network was first created or how long its operators had been using it.
A distributed operation rather than one obvious source
PaperPhone does not send all its requests from a single server, address or country. Its traffic is spread across tens of thousands of IP addresses, making it harder for defenders to identify a clear source and block the activity with a small set of network rules.
The geographic distribution is a central feature of the operation. A website could receive related requests that appear to originate from numerous countries, even though CrowdSec’s analysis indicates that they are part of the same coordinated cluster.
This scale also reduces the usefulness of one-off IP bans. Blocking an address after detecting suspicious behaviour may stop a small portion of the traffic, but the operator can continue making requests through many other addresses within the wider pool.
How PaperPhone headless-browser traffic works
A headless browser is browser software that operates without the visible interface normally used by a person. It can load web pages, process site content and issue requests automatically. Legitimate uses include software testing and monitoring, but headless browsers can also support large-scale automated activity.
The PaperPhone network combines browser automation with fabricated mobile identities. Instead of consistently presenting one recognisable automation profile, requests repeatedly claim to come from different phones and browsers. This makes the traffic appear more like a varied population of genuine mobile users.
The technique creates several layers of apparent diversity:
- Requests are distributed across approximately 75,000 IP addresses.
- The addresses span 230 IP blocks rather than one narrow hosting range.
- Traffic appears to originate from 43 different countries.
- Requests present changing phone and browser identities.
- Automated browser behaviour is made to resemble ordinary mobile access.
These characteristics undermine filters that evaluate only a request’s IP address, stated location or claimed device. Each individual request may look unremarkable when considered in isolation. The relationship becomes clearer only when defenders compare behaviour and identity patterns across a larger body of traffic.
Why fabricated mobile identities matter
Web services routinely use browser and device information to understand incoming traffic. A request that claims to come from a familiar mobile browser can appear less suspicious than one that openly identifies an automation framework.
PaperPhone exploits that assumption by repeatedly presenting fabricated phone and browser combinations. An IP address may be new to the target, while the associated identity also appears plausible. The result is a stream of automated requests that is harder to separate from legitimate mobile visits using simple rules.
This does not mean every request can perfectly reproduce a real user. Behavioural inconsistencies may still expose automation, including repeated navigation patterns, unusual request timing or mismatches between claimed device characteristics and browser behaviour. CrowdSec’s findings show why those signals need to be assessed together rather than relying on a single attribute.
Who is affected by the PaperPhone network
The reporting does not identify a specific victim, industry or geographical target. Any organisation operating a publicly accessible website could encounter this type of traffic, particularly if it relies heavily on basic IP reputation, country blocks or static browser identity checks.
No affected software product or vulnerable version has been named because PaperPhone is not described as exploiting a particular software flaw. It is a traffic evasion operation that uses automation and distributed infrastructure. Organisations therefore cannot resolve the issue by applying one vendor patch.
The source material also does not establish the operator’s final objective for every automated request. Headless-browser networks can be used for different tasks, but assigning a specific purpose to PaperPhone without supporting evidence would overstate the published findings.
Current exploitation status
As reported on 29 September 2026, CrowdSec had observed and analysed the cluster using bot signals collected after its 31 August detection update. The scale of the identified infrastructure indicates an operational network rather than a limited laboratory demonstration.
There is no reported confirmation that the network has been dismantled or that all associated infrastructure is inactive. Equally, the available report does not show that every one of the 75,000 addresses remains active simultaneously. The figure represents the addresses connected to the observed cluster during the investigation.
Why this distributed browser operation matters
The PaperPhone network demonstrates a practical weakness in controls that treat IP addresses as stable identities. When one operator can distribute activity across thousands of addresses and dozens of countries, blocking isolated sources becomes a reactive process with limited effect.
The event is particularly relevant to organisations whose web defences allow or deny requests mainly according to location, IP reputation or claimed browser details. Those signals remain useful, but PaperPhone shows that they should not be treated as decisive evidence that a request is genuine.
How organisations should respond
Defenders should first determine whether unusual mobile traffic contains repeated behavioural patterns across changing IP addresses. Reviewing request timing, navigation sequences, browser characteristics and application-level actions together may reveal connections that are invisible in individual logs.
Measures directly relevant to this event include:
- Use bot management that evaluates behaviour as well as IP reputation.
- Correlate activity across sessions, addresses, countries and claimed devices.
- Check for inconsistencies between mobile identities and observed browser capabilities.
- Apply proportionate rate controls to sensitive web functions.
- Monitor whether blocks simply cause similar requests to move to new addresses.
The goal is not to reject mobile traffic or block entire countries without context. It is to recognise coordinated automation even when its network location and presented identity keep changing. PaperPhone illustrates why layered web defence is more reliable than any single IP, location or device check.
Originally reported by cybersecuritynews.com.


